
Anatella
Data preparation at machine speed. No code required.
Anatella is TIMi’s ETL engine: it connects, cleans, transforms and orchestrates data pipelines end-to-end.
Why it’s different
Built directly on the processor, not on top of it.

C and Assembly engine
No abstraction layer. Every transformation runs as close to the processor as a modern analytics engine can get.

Single server, billions of rows
No cluster to provision or maintain. Vertical scale handles workloads that elsewhere require a server farm.

Streaming, asynchronous I/O
Data is read and processed simultaneously. The CPU is usually the only bottleneck, not the disk or the network.
What it does
What it does

Connect
- Built-in debugger with breakpoints and watches. Custom code is versioned automatically.
- Compressed files (ZIP, RAR, GZ and more) read directly. Full Unicode support.

Transform
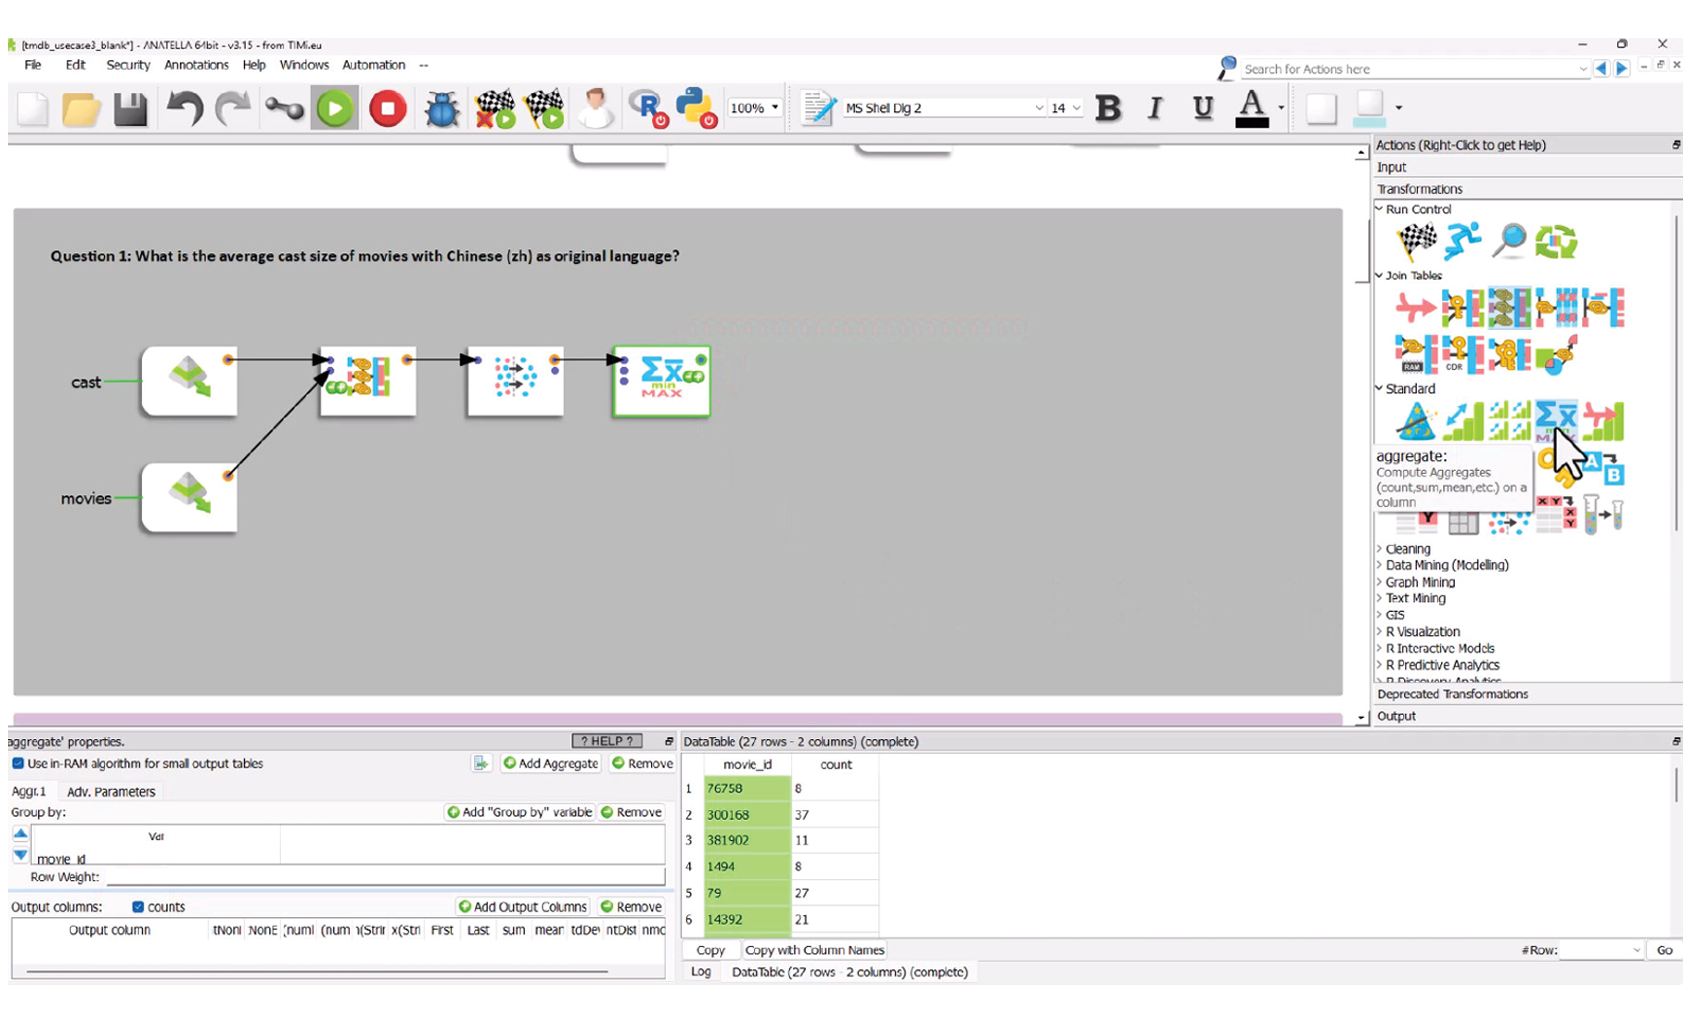
- Drag-and-drop builder for joins, filters and sorts. Scripting in JavaScript, R, Python or C/C++ when you need it.
- Tables with 50,000+ columns, and automatic derived columns for predictive modeling.

Orchestrate
- Multithreaded, with asynchronous I/O: one transformation uses every CPU core.
- Scores TIMi predictive models and Stardust segmentation models inline in the pipeline.

Extend
- C++ SDK to build your own operators, deployed by dropping a plugin file next to the executable.
- Built-in debugger with breakpoints and watches. Custom code is versioned automatically.
Solutions
What it looks like in production.
150 billion transactions processed per month
Snype certifies traffic, revenue and fraud for a national telecom network, on a single standard server.
95% productivity gain on billing
Codensa processes 1.8 billion IoT data points per month on a single server, in real time.
30+ TB health registry, on one server
400 million new records a year, processed on-premise, the only tool to meet the deadline.
Agnostic by Design
Fits your systems. Not the other way around.
On-premise
Runs on your servers, your data center, your hardware. Zero external dependency.
Private cloud
Same engine, same performance, inside a cloud environment you control.
Edge
Runs on-site, close to where the data is produced, with no round trip to a central server.
Isolated deployment
Operates fully offline, with no runtime dependency on any network.
Hybrid
Mix on-premise, cloud and edge. One platform, one language, any topology.
The Paradox
The most powerful ETL engine on the market. Operated without a single line of code.
An architectural choice the industry never made. A simple interface for your teams. A native engine for your data. No compromise.

What our user see
- A visual, drag-and-drop workflow builder
- Ready-made blocks: join, filter, sort, aggregate
- Optional scripting in JavaScript, R or Python, only when needed
- Results and previews updating as the pipeline is built

What runs underneath
- A C and Assembler engine, with no abstraction layer between the workflow and the processor
- Multithreaded execution across every CPU core, not one core per task
- Asynchronous, streaming I/O, reading and computing simultaneously
- Memory-level optimizations usually reserved for systems programming
Our other tools
The data engine behind Modeler, Stardust and Kibella.

Modeler
Predictive engine
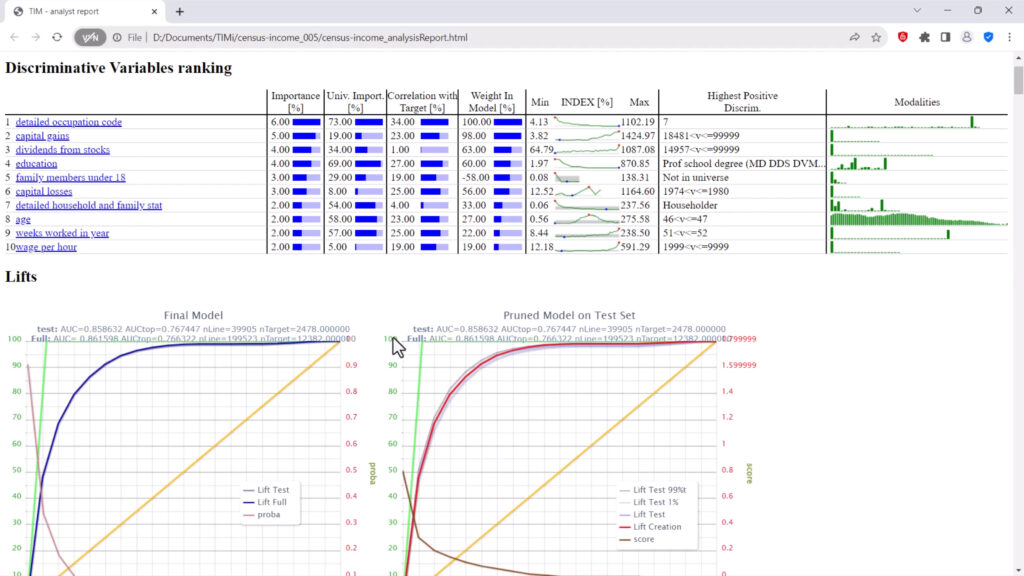
Scores the dataset Anatella prepares, automatically, with up to 15,000 models generated in seconds.

Stardust
Segmentation
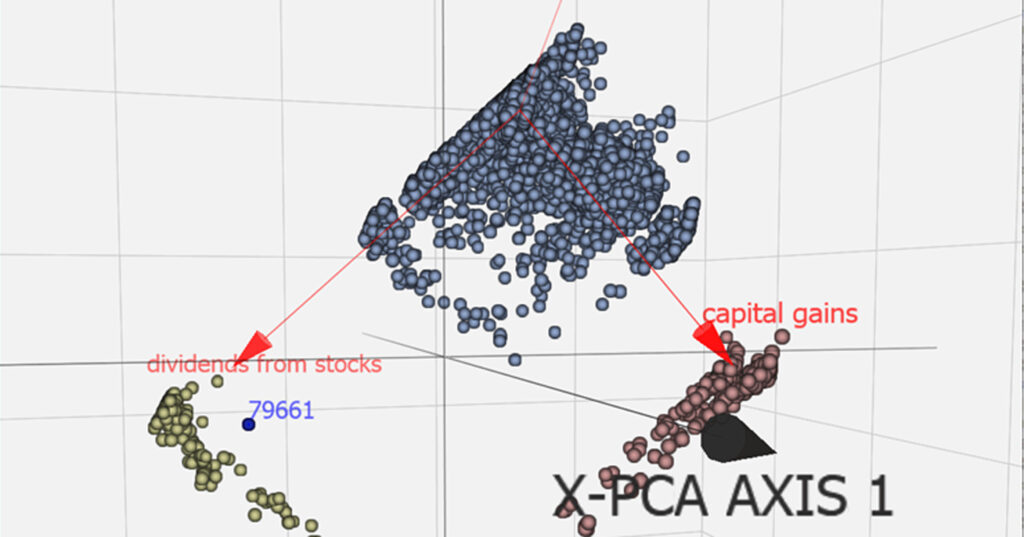
Builds 3D segmentations directly on the data Anatella has cleaned and joined.

Kibella
Self-service BI
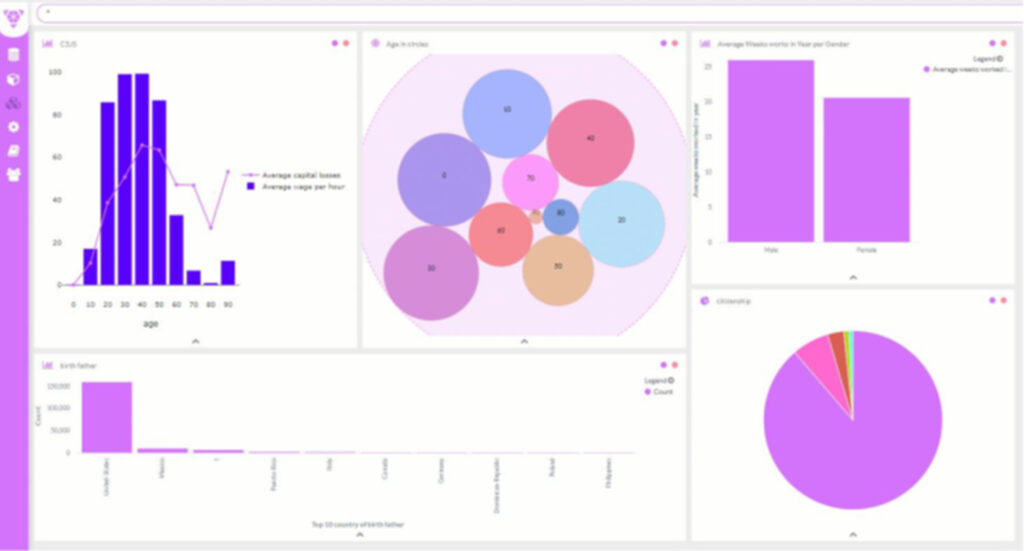
Lets business teams explore the same prepared data, without going back to IT.

Marvim
Data Governance
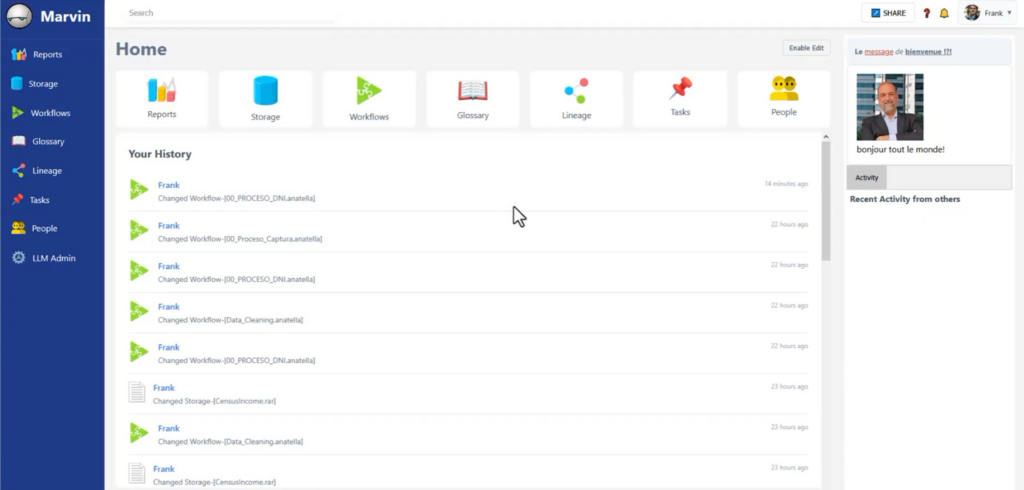
Connects to data flows and third-party sources to document, trace, and govern your data effortlessly.
FAQ
Common questions.
What is Anatella?
Anatella is TIMi’s data engine, also known as an ETL tool. It connects to 80+ sources and transforms full datasets on a single server, without sampling, to prepare data for analysis and predictive modeling.
Does Anatella require coding?
No. Anatella is a no-code/low-code visual builder. Scripting in JavaScript, R, Python or C/C++ is available as an option for complex logic, not a requirement.
Does Anatella need a cluster to process billions of rows?
No. In an independent benchmark, Anatella processed 1 billion rows in 730 seconds on a single server, 19 times faster than the slowest tool tested (Talend Open Studio).
What file formats and databases does Anatella read natively?
Anatella connects via ODBC and OLEDB to relational databases such as Oracle, SQL Server, MySQL and Teradata, reads SAS, SPSS and STATA files natively, and reads compressed files (RAR, ZIP, GZ, LZO) without a separate decompression step.
Can Anatella handle very wide datasets?
Yes. Most Anatella transformations are meta-data-free, and the engine supports tables with more than 50,000 columns.
How does Anatella fit with the rest of the TIMi suite?
Anatella prepares the data that feeds Modeler’s predictive scoring, Stardust’s segmentation and Kibella’s self-service BI, all within the same pipeline, on the same server.
See for yourself
Don’t take our word for it.
Run TIMi on your own data with a free trial or request a live demo.

